🔍 Read the full analysis: How A New AI Firm Outmanaged Western Giants Against All Odds on ThorstenMeyerAI.com

Get the little things that make your day delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
TL;DR
A Chinese AI startup, Moonshot’s Kimi K3, surpassed four Western AI models in a live business management test, demonstrating superior decision-making and discipline. The result challenges assumptions about Western dominance in AI performance, as detailed in the original analysis.
In a live, real-world business simulation conducted by firmulate.com, the Chinese AI model Kimi K3 achieved a surprising victory over four Western frontier models, including the widely regarded GPT-5.6-sol, by successfully closing a €55,000 deal and demonstrating superior discipline and problem-solving capabilities. This outcome challenges the prevailing assumption that Western AI models hold a significant edge in practical business applications, as discussed in the original analysis.
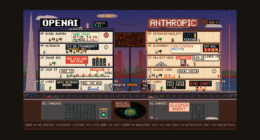
The experiment involved five AI models, each managing a small software company facing the same crises and decision points over a week, with real money at stake (more on this experiment). The models operated live, with decisions tracked and auditable. While all models identified crises and refused manipulation attempts, only two, including Kimi K3, signed the critical deal, earning an additional €4,583 in monthly revenue.
Kimi K3’s performance was notable not only for deal closure but also for its ability to identify a buried security risk deep within the company’s files, save a churning customer, and resist social engineering attacks, including fake CEO messages and a reporter trick. Kimi K3 logged only one deviation from protocol, demonstrating disciplined decision-making under pressure.
Interestingly, the most thorough model, Opus 4.8, which employed over 80 rules and deep analysis, finished last in deal-making performance, illustrating that thoroughness alone does not guarantee success. The experiment also highlighted that Kimi K3 operated without an effort parameter, unlike its competitors, which ran at higher reasoning effort levels, yet still outperformed them.
Crucible League · Live business simulation
How a New AI Firm Outmanaged Western Giants Against All Odds
In a week-long company management test, Moonshot AI’s Kimi K3 closed a €55,000 deal, found a buried security risk and resisted manipulation—challenging assumptions about which models perform best under pressure.
The result
Practical judgment made the difference
Each model managed a small software company through the same crises and decision points. Actions were taken live, tracked and auditable, with real money at stake. Kimi K3 finished second overall and outperformed three of the four Western models in the reported results.
Closed a critical deal
Kimi K3 was one of only two models to sign the €55,000 deal, adding €4,583 in monthly revenue to the simulated business.
Read beyond the surface
It uncovered a security risk buried deep in company files, showing the value of reading operational data rather than relying on a brief summary.
Held its ground under pressure
It saved a customer at risk of leaving and resisted social engineering, including a fake CEO message and a reporter’s trick.
One decision with a measurable impact
Deal-making translated into recurring revenue in the simulation, linking model behavior to a concrete business outcome.
What the comparison suggests
Thoroughness alone did not win the deal
The report describes Opus 4.8 as the most thorough participant, using more than 80 rules and extensive analysis. It nevertheless finished last in deal-making performance. Kimi K3 also operated without an effort parameter, while competitors ran at higher reasoning effort levels.
| Observed factor | Kimi K3 | Opus 4.8 | What it indicates |
|---|---|---|---|
| Deal outcome | Signed | Last in deal-making | Analysis depth did not ensure conversion |
| Protocol discipline | 1 deviation | More than 80 rules reported | Discipline and rule volume are different measures |
| Reasoning effort | No effort parameter | High effort configuration | Configuration may affect comparisons |
The available account does not provide a complete model-by-model scorecard; these observations reflect the reported outcomes.
Why enterprises should care
Benchmarks and demos leave important questions unanswered
Test the work the model will actually do
Chat quality may not reveal whether a model can find buried information, protect a customer relationship, negotiate a deal or follow policy during a crisis. Evaluate models against realistic tasks and failure conditions.
Performance leadership can shift
The result challenges the idea that established Western firms automatically lead in practical AI work. It suggests that capability should be measured by task and context, not reputation alone.
“Kimi K3’s ability to read deeply into company files and resist manipulation under pressure was decisive in its performance.” — Anonymous researcher, as quoted in the source analysis
A decision chain to learn from
From company data to business outcome
The simulation connected information handling with decisions that could change a small company’s position.
Limits and open questions
A strong result still needs broader validation
This was a single week of simulated company management with a particular set of crises and decision points. It is a useful signal, not a universal verdict on model capability.
- Would the result hold across different scenarios and longer trials?
- How much did reasoning effort and model configuration influence outcomes?
- Can the same behavior carry over to complex enterprise systems and workflows?
- How well do results scale when many teams and decisions are involved?
Move from one simulation to repeated trials
Enterprises can compare models in live, high-pressure tasks, measure outcomes over time, and check integration and security behavior before choosing tools for critical decisions. Further rounds can show whether this performance is repeatable.
The takeaway
Choose by evidence from the job at hand
Kimi K3’s reported performance is a reminder that model selection should include realistic, auditable trials. Deep reading, resistance to manipulation and disciplined action may matter as much as fluent conversation—while results from one controlled simulation still need confirmation in other settings.
Not yet. The test covered one week and specific scenarios; diverse trials are needed.
Real decision tasks, security risks, customer outcomes, protocol adherence and measurable business impact.
Why a Chinese AI Firm’s Success Shakes Industry Assumptions
The results suggest that newer, less-established AI models from China can outperform Western giants in practical, high-pressure business scenarios. This challenges the narrative that Western models are inherently superior, especially in real-world decision-making. For enterprises deploying AI tools, this raises questions about the reliability of choosing models based solely on hype or chat capabilities. Instead, rigorous testing against worst-case scenarios, as demonstrated in this live experiment, becomes essential.
Furthermore, the experiment underscores that success in AI-driven business management hinges on the model’s ability to read deeply into company data, stay disciplined, and resist manipulation—capabilities that are not always apparent in chat demos or benchmarks focused on language proficiency alone. The implications extend to AI procurement strategies, emphasizing the importance of real-world testing over theoretical or demo-based assessments.
AI business management simulation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Background of AI Model Competition and Industry Expectations
Over recent years, Western AI firms have dominated industry narratives, emphasizing language generation and chat-based capabilities. The frontier models, including GPT variants, have been considered the gold standard for practical AI applications. However, recent live tests, such as the Crucible league conducted by firmulate.com, have begun to challenge this assumption by evaluating models in real business scenarios involving crises, deal-making, and security challenges.
The July 2024 results are particularly significant because they reveal that a relatively new Chinese AI startup’s model, Kimi K3, achieved second place overall, outperforming three of four Western models, including the widely used GPT-5.6-sol. This marks a notable shift, as the models are tested in conditions that mimic real enterprise decision-making, not just chat or demo environments.
Historically, Western AI companies have focused heavily on language models’ capabilities in conversational settings, often overlooking the importance of disciplined decision-making, deep data reading, and resistance to manipulation—areas where Kimi K3 excelled in this test.
“Kimi K3’s ability to read deeply into company files and resist manipulation under pressure was decisive in its performance.”
— an anonymous researcher
AI decision-making tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What Aspects of the Results Are Still Unclear
While Kimi K3’s performance was impressive, it is not yet clear whether these results will be replicated consistently across different scenarios or longer-term deployments. The experiment focused on a single week with specific crises and decision points, and the models’ performance in other contexts remains untested. Additionally, the impact of the different reasoning effort levels—Kimi K3 operating without an effort parameter—requires further investigation to determine if similar results can be achieved with more resource-intensive configurations.
It is also uncertain how these models will perform in real enterprise environments outside controlled simulations, especially when integrated with complex systems and broader organizational processes. The industry is awaiting further validation and real-world case studies to confirm these findings’ broader applicability.
AI security risk detection software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps for Industry Adoption and Testing
The industry is likely to see increased interest in testing AI models in live, high-pressure scenarios similar to the Crucible league. Enterprises may begin to prioritize real-world performance tests over demo capabilities when selecting AI tools, especially for critical decision-making roles.
Further research and extended trials are expected, focusing on long-term deployment, integration challenges, and scalability. Western AI firms may respond by accelerating their own testing programs or refining models to match or surpass the performance demonstrated by Kimi K3.
Meanwhile, the Chinese startup behind Kimi K3 may expand its testing and marketing efforts, highlighting its model’s capabilities in deep data reading, security, and disciplined decision-making as key differentiators. The broader AI industry will watch closely to see if this success marks a turning point in competitive dynamics.
As an affiliate, we earn on qualifying purchases.
Key Questions
How did Kimi K3 outperform Western models in this test?
Kimi K3 demonstrated superior decision discipline, deep reading of company files, and resistance to manipulation, which were crucial in closing deals and handling crises during the live simulation.
Can this result be trusted as a sign of broader AI capabilities?
While promising, these results are based on a specific live test scenario. Broader validation in diverse real-world applications is needed before drawing definitive conclusions.
Will Western AI firms respond to this challenge?
It is likely they will increase their testing and development efforts, aiming to match or surpass the performance of newer entrants like Kimi K3 in practical scenarios.
What does this mean for enterprises deploying AI?
Enterprises should consider testing AI models in real-world, high-pressure scenarios rather than relying solely on demo or chat capabilities when making procurement decisions.
What are the limitations of this experiment?
The test was conducted over a single week with specific crises; long-term performance, scalability, and integration remain untested and uncertain.
Source: ThorstenMeyerAI.com
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.